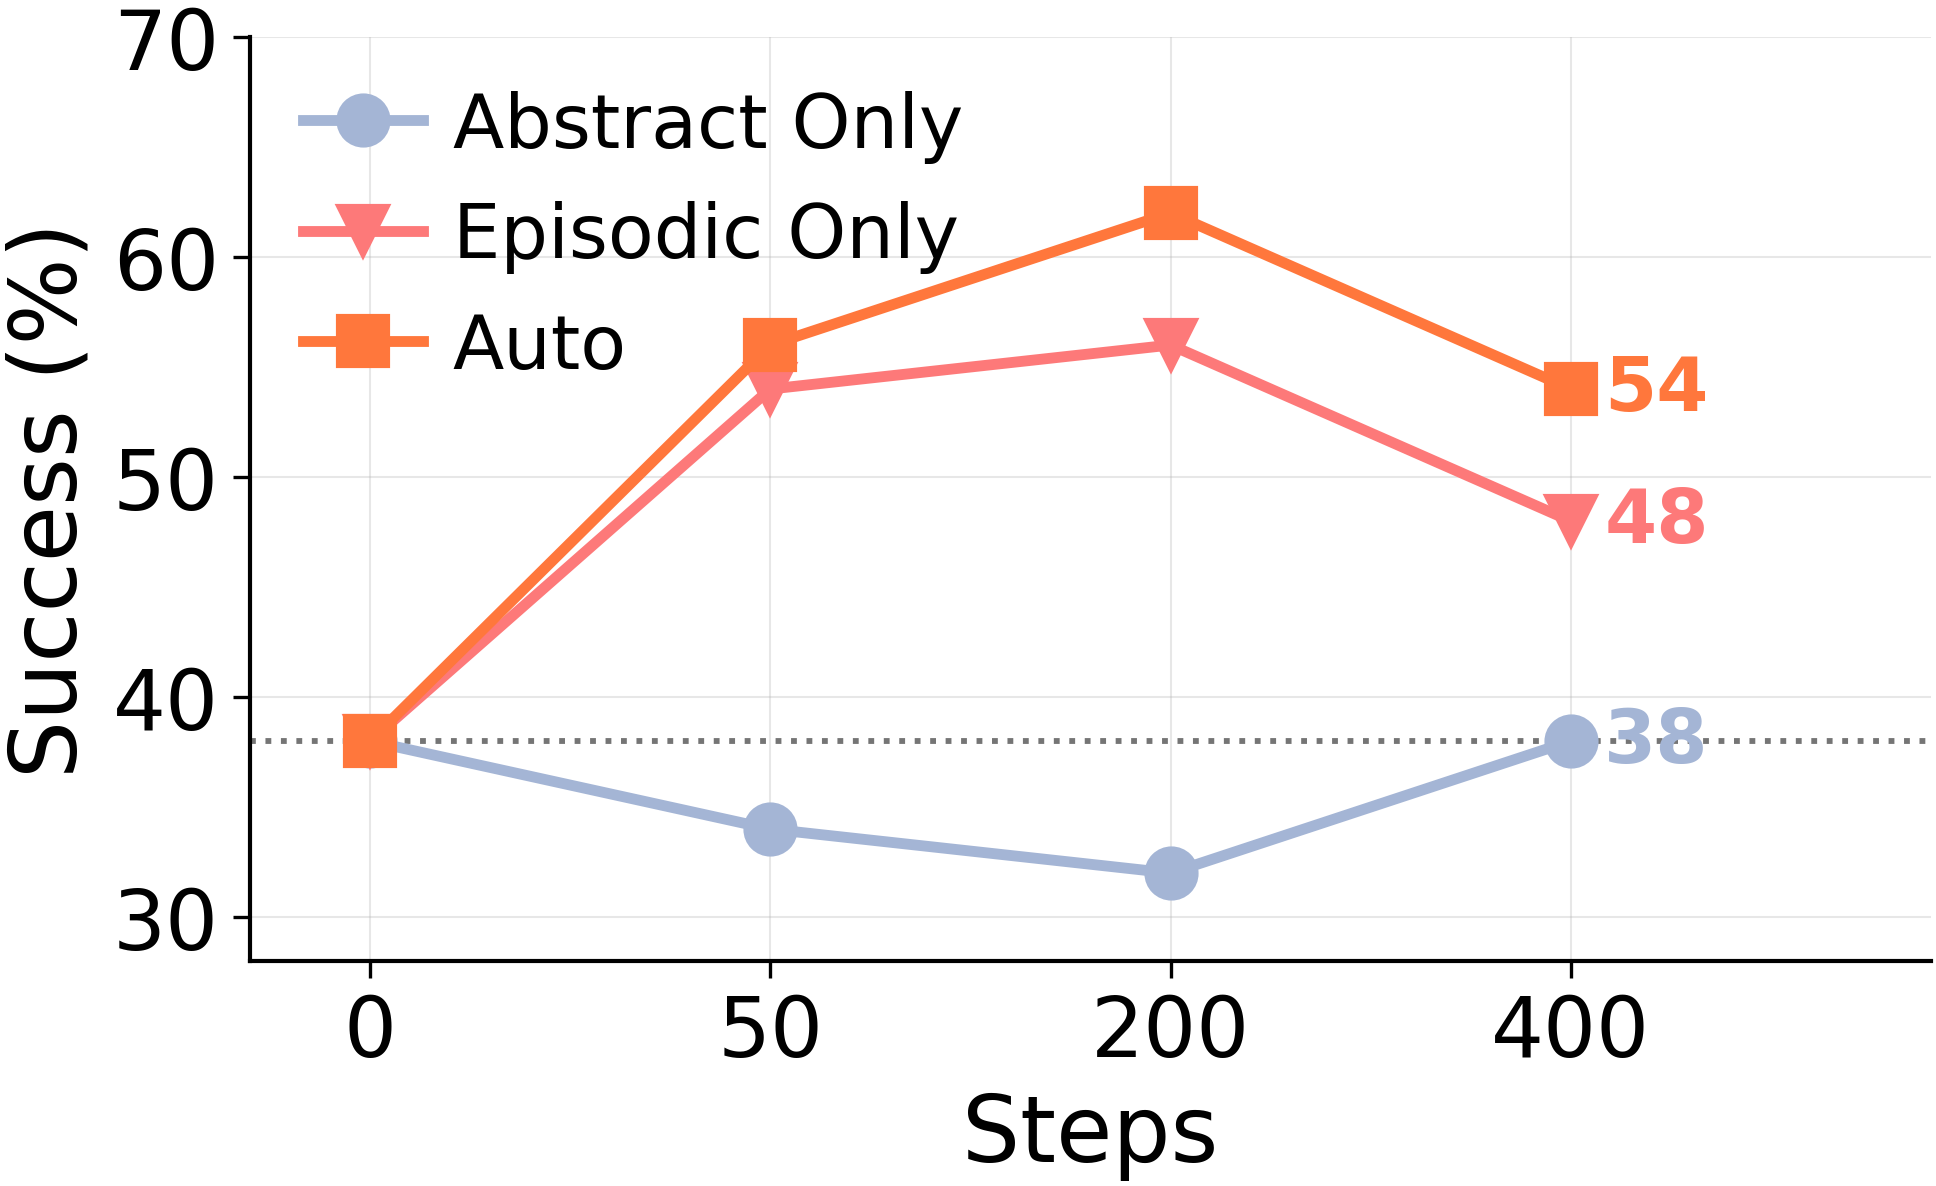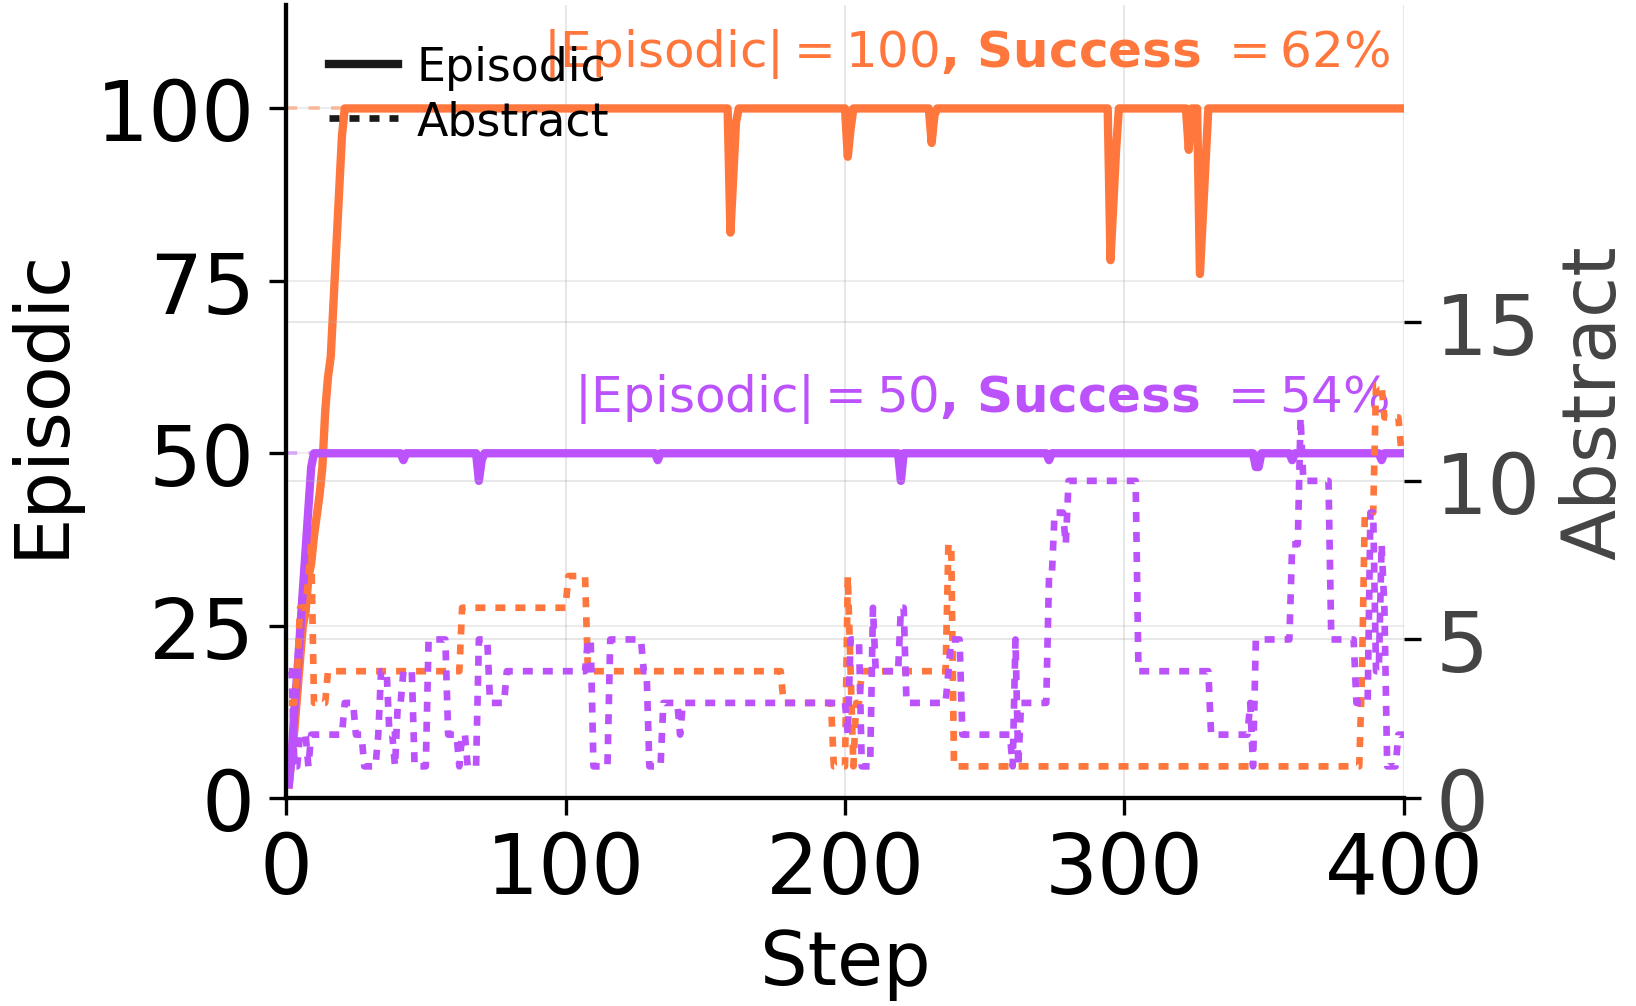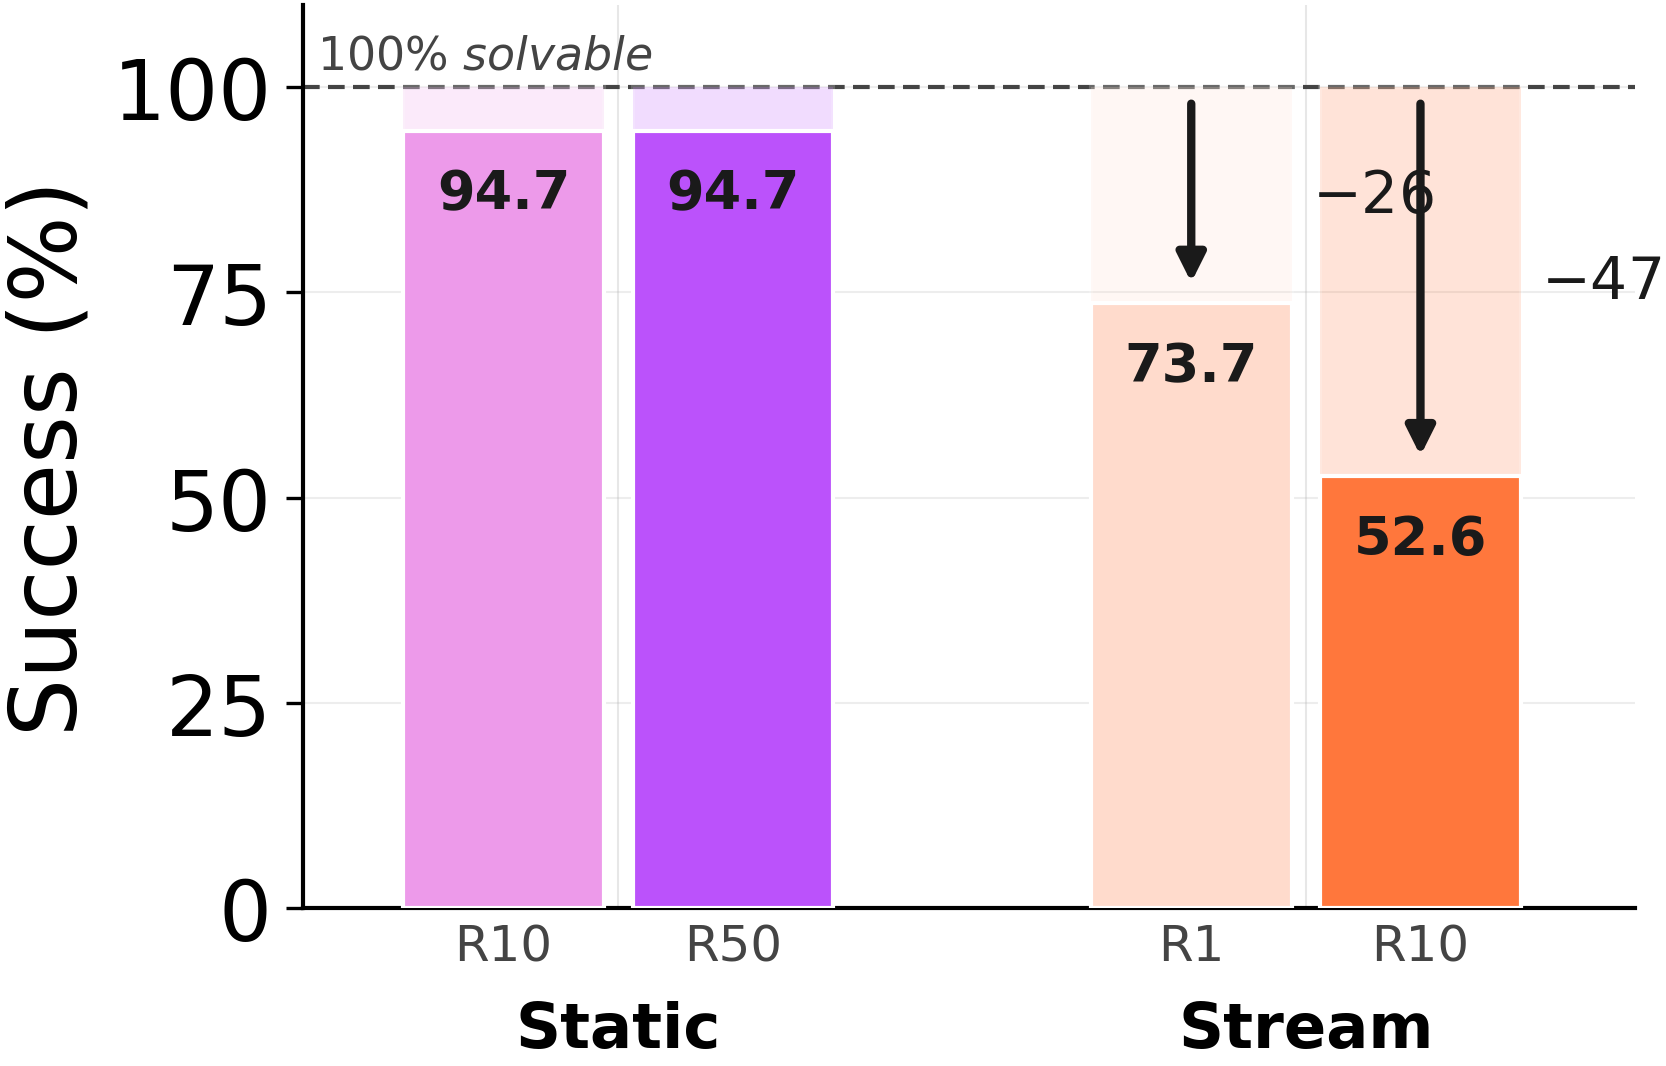
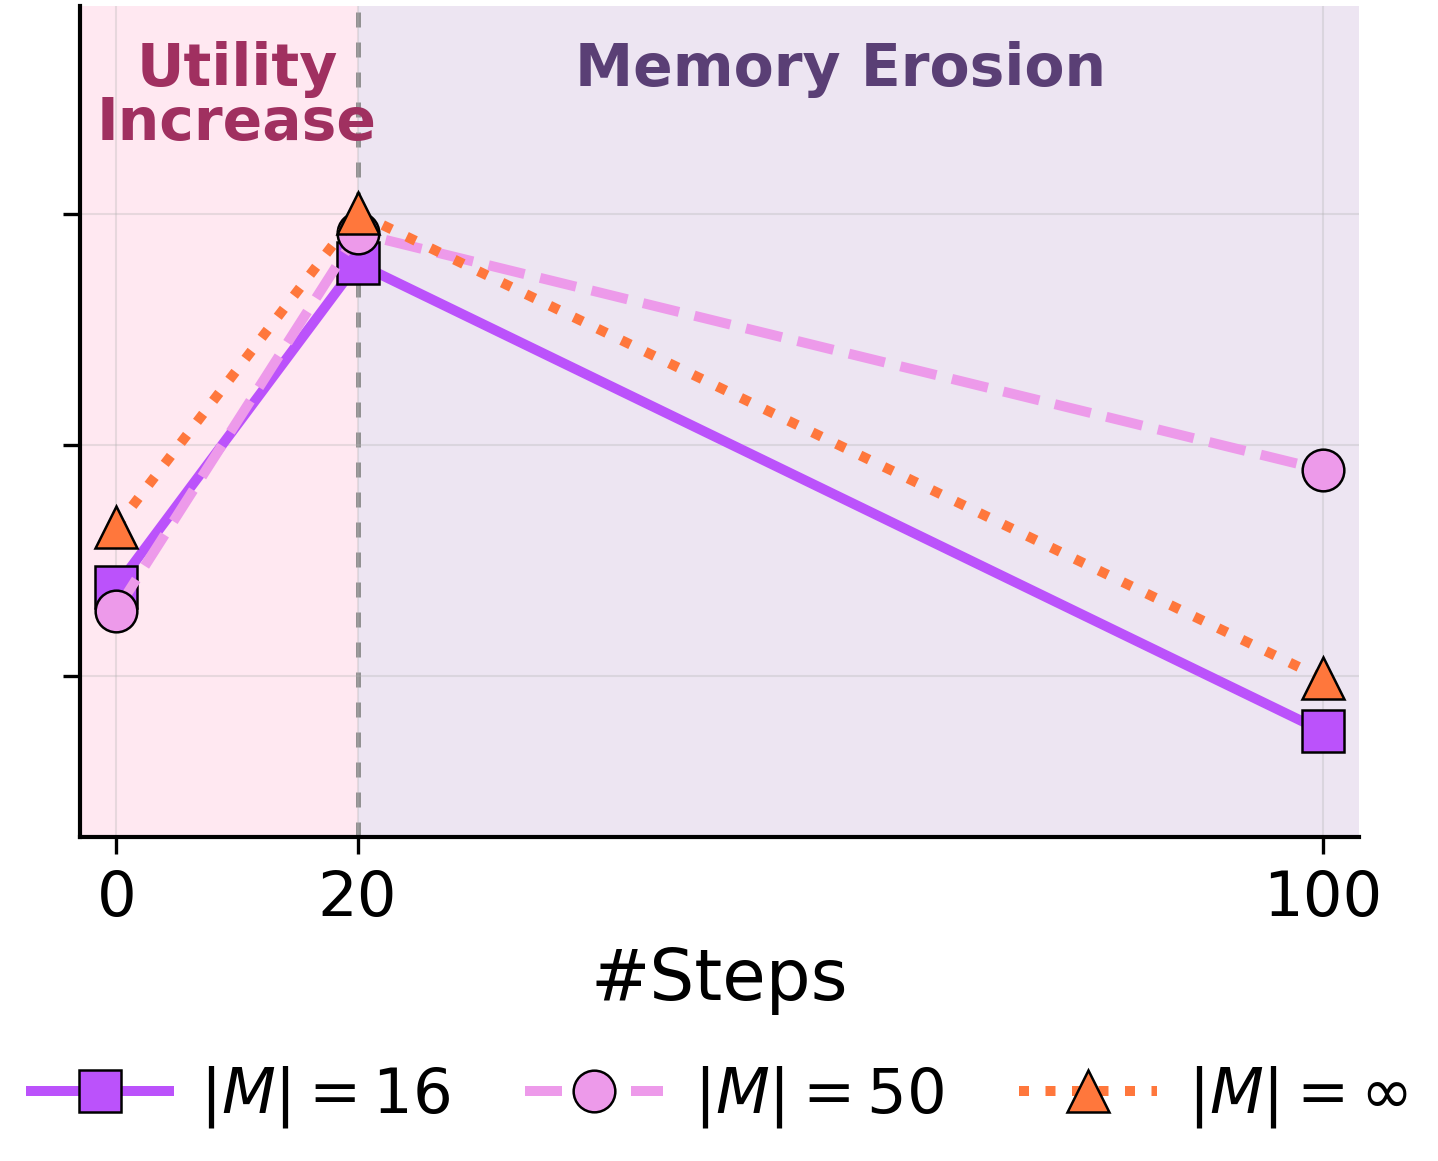
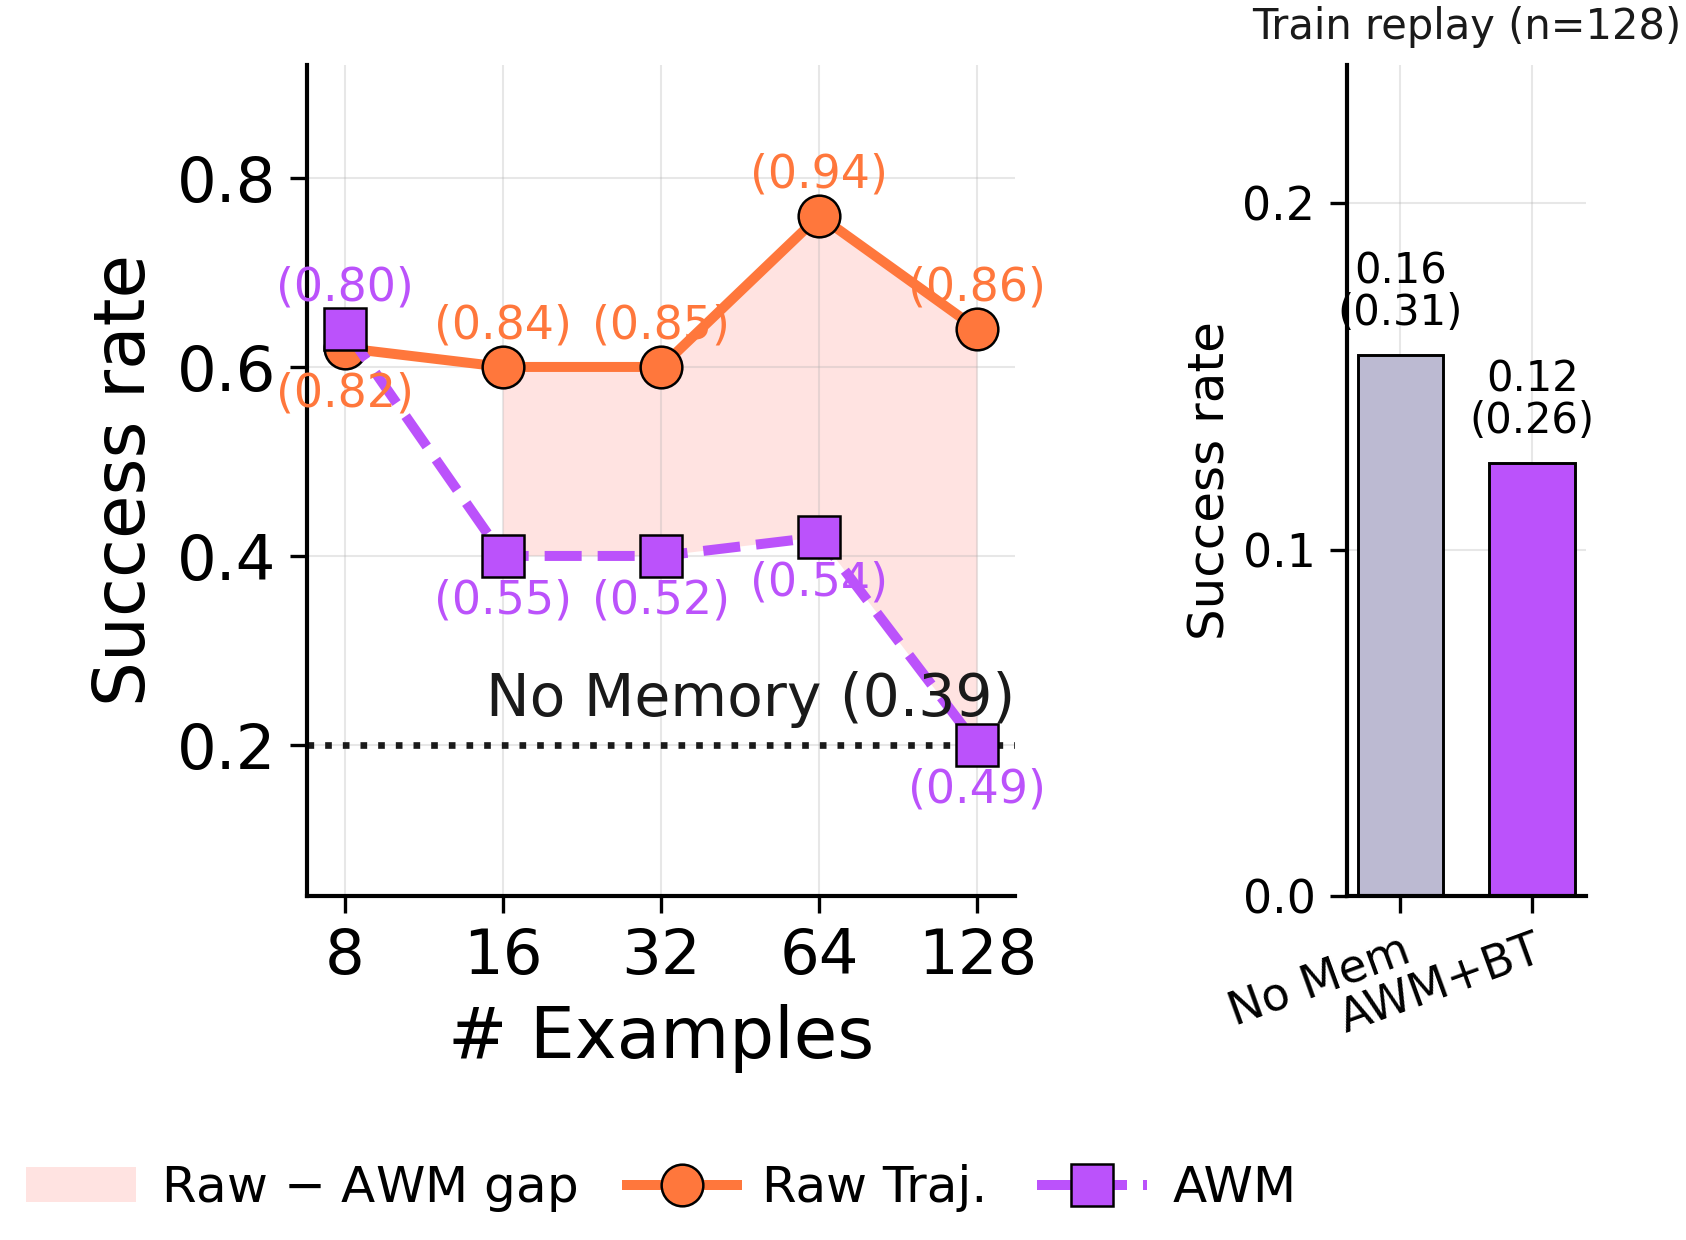
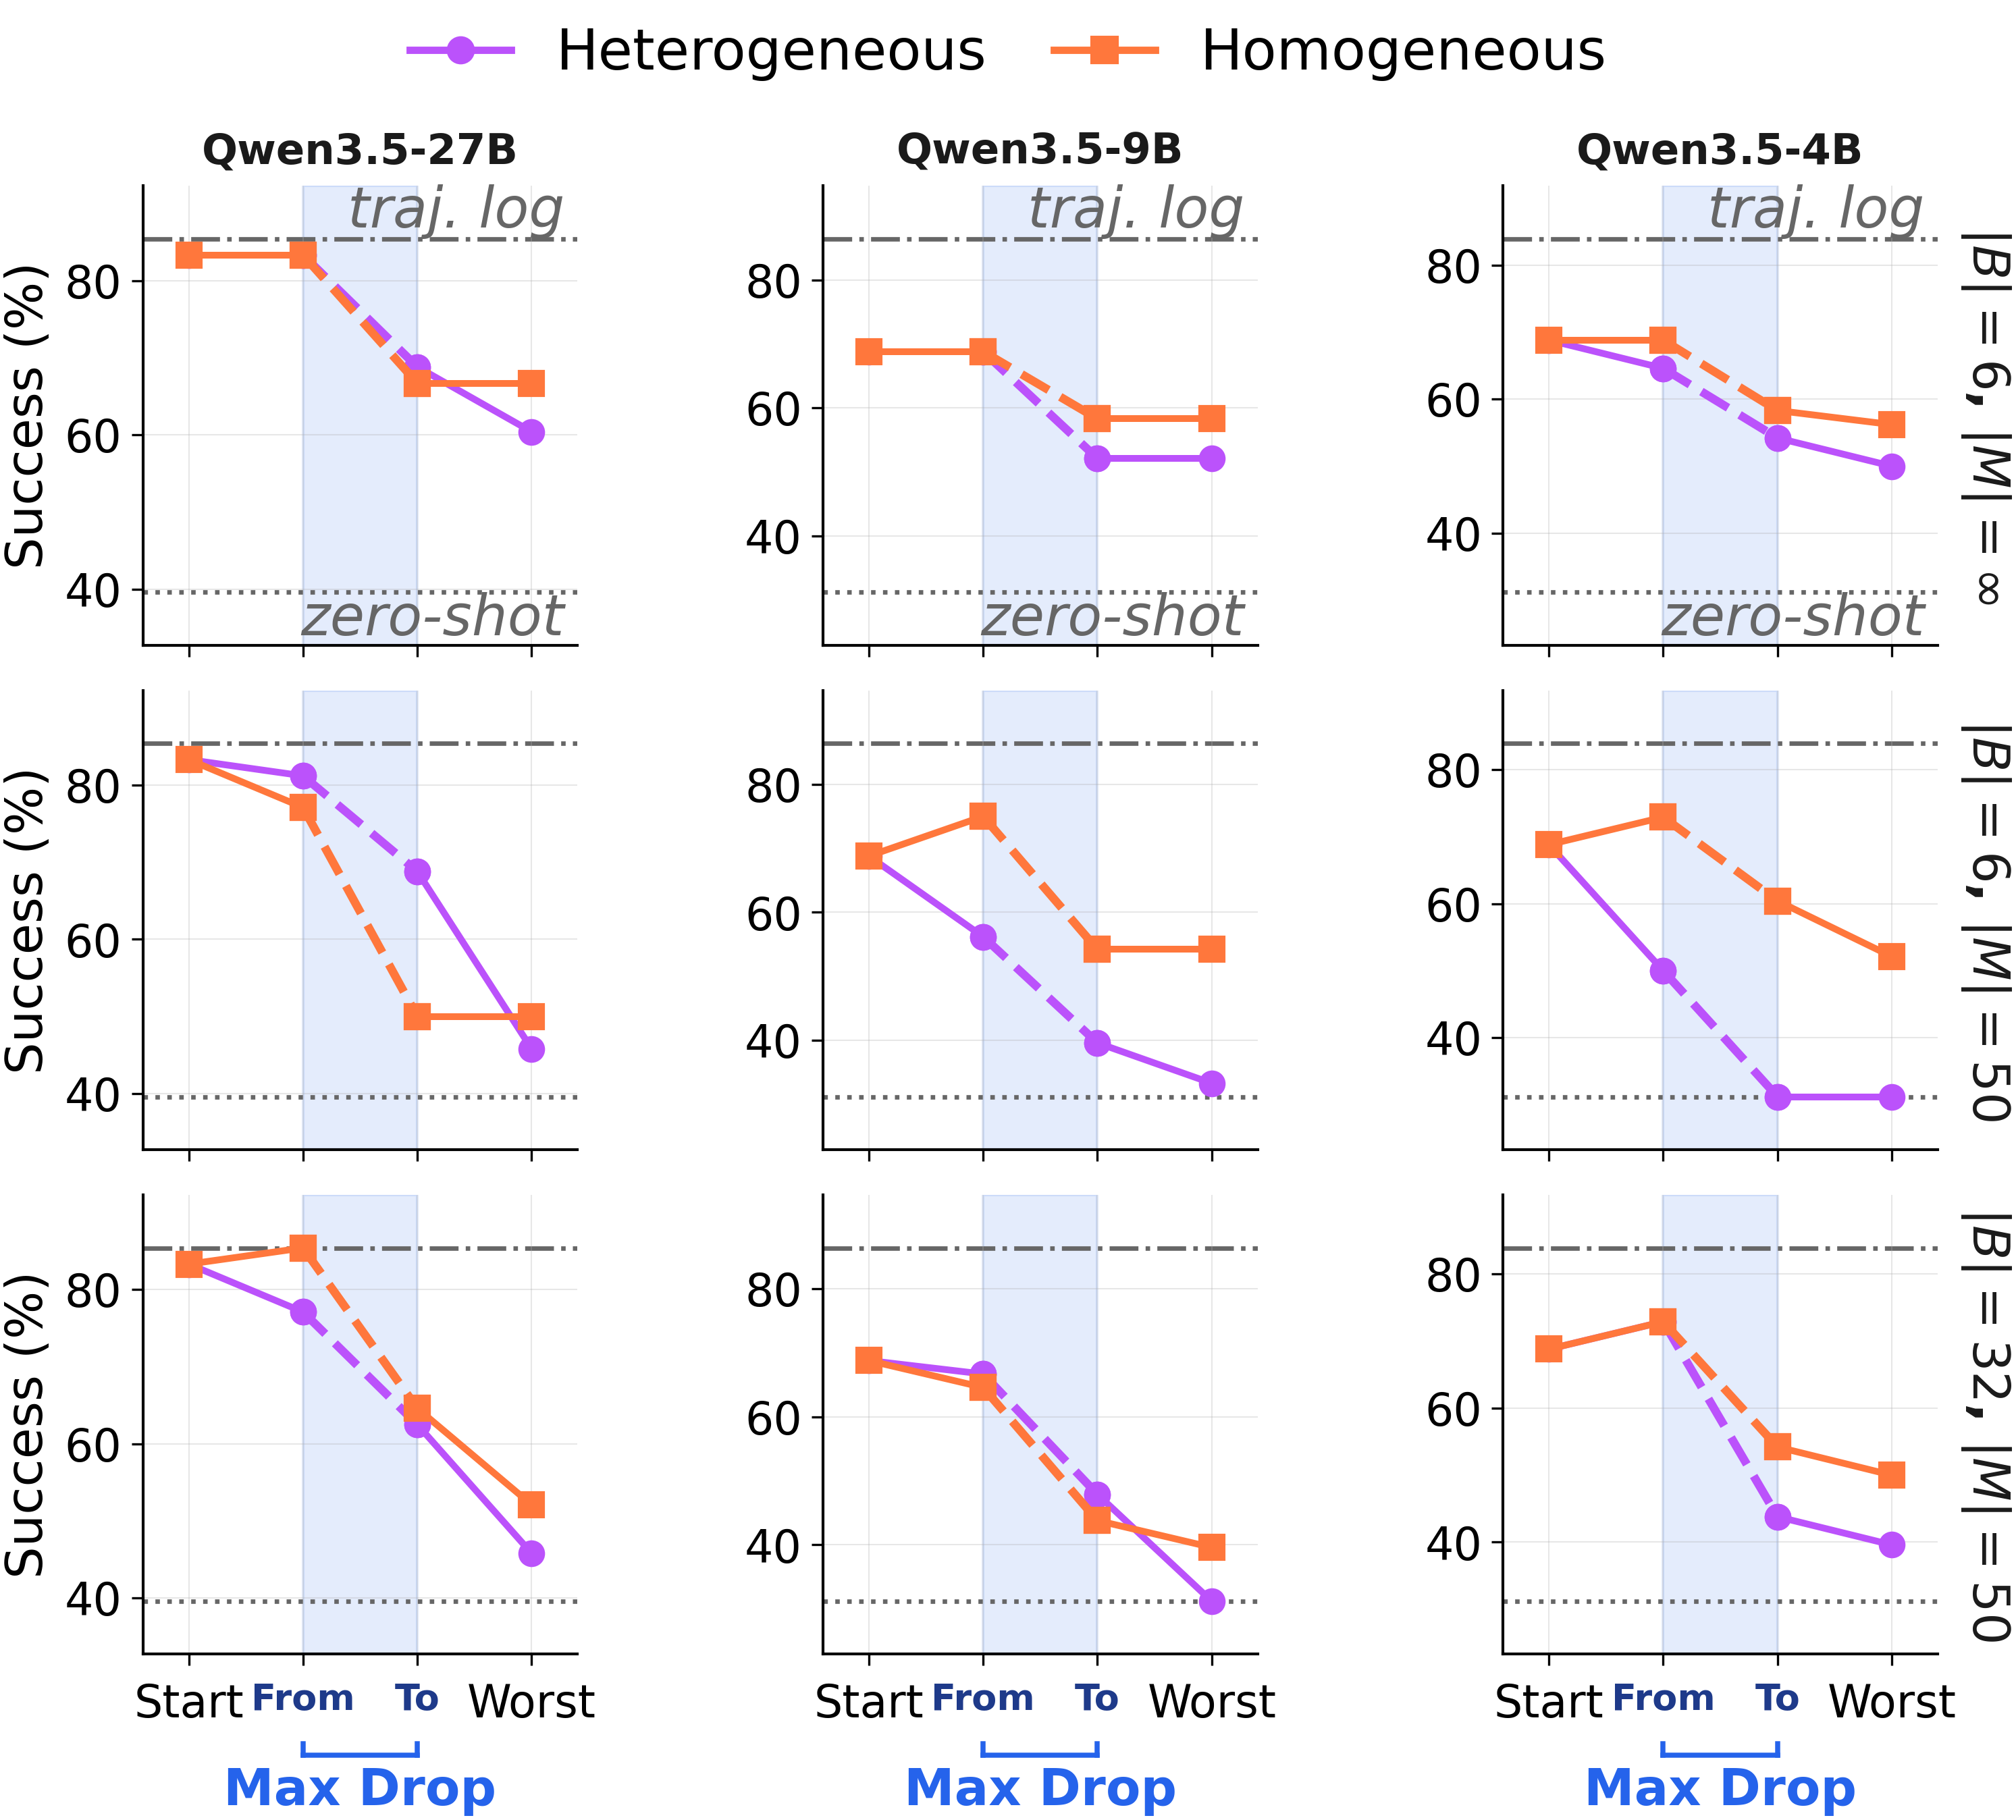
PropWorld keeps every fact fixed. Utility still falls.
PropWorld is a synthetic crafting benchmark designed to make memory failure auditable. Each episode names an opaque environment, describes an item with nonce-valued attributes, and asks the agent to choose a tool. In Base-1, eight environments each hide one fixed eight-value lookup table: 64 mappings total. One correct lookup ends the episode; nothing in the world drifts.
To remove upstream trajectory errors, each memory updater receives a correctly solved interaction and the correct action—but never the hidden rule table. Evaluation freezes memory and reuses the same clean 64-item exam, built from held-out item combinations whose values appeared in training. A rise-then-fall curve therefore points to how persistent text is maintained or retrieved, not to a changing task.
Opaque environments, fixed value-to-tool mappings.
Correct trajectory and action; no hidden rule table.
The same coverage exam at every checkpoint.
LangMem's bank grew from 84 records at update 48 to 573 at update 768 for only 64 fixed mappings. The documented interpretation is semantic crowding: loose deduplication can fill top-10 retrieval with near-neighbors, making the useful record harder to surface. This widens the failure model: full rewrites can alter what is stored, while append-and-update systems can also degrade how effectively stored text is consumed. Both can turn more maintained text into less usable knowledge.
Scope. These are single-seed Qwen3.6-27B trajectories. LangMem and ReasoningBank use Base-1; Dynamic Cheatsheet comes from a separate fixed 12-environment mixed suite. The LangMem score curve stops at the last clean checkpoint, update 144: later checkpoints are excluded because the curator began returning repeated GraphRecursionError failures. The record-count diagnostic is reported separately through update 768. In a separate 20 % corruption stress test, Letta fell from .812 to .375 while its matched clean run remained near .9.